
A data estate is all the data a company holds, together with the systems that collect, store, process and present it. Getting it in order means knowing what is in it and who depends on each part. The spending follows from that.
This guide explains what a data estate includes, how one drifts out of order as a company grows, the signs to look for, and a practical sequence for fixing it. It is written for data leaders and engineers at companies whose data has grown faster than the team looking after it.
What a data estate is
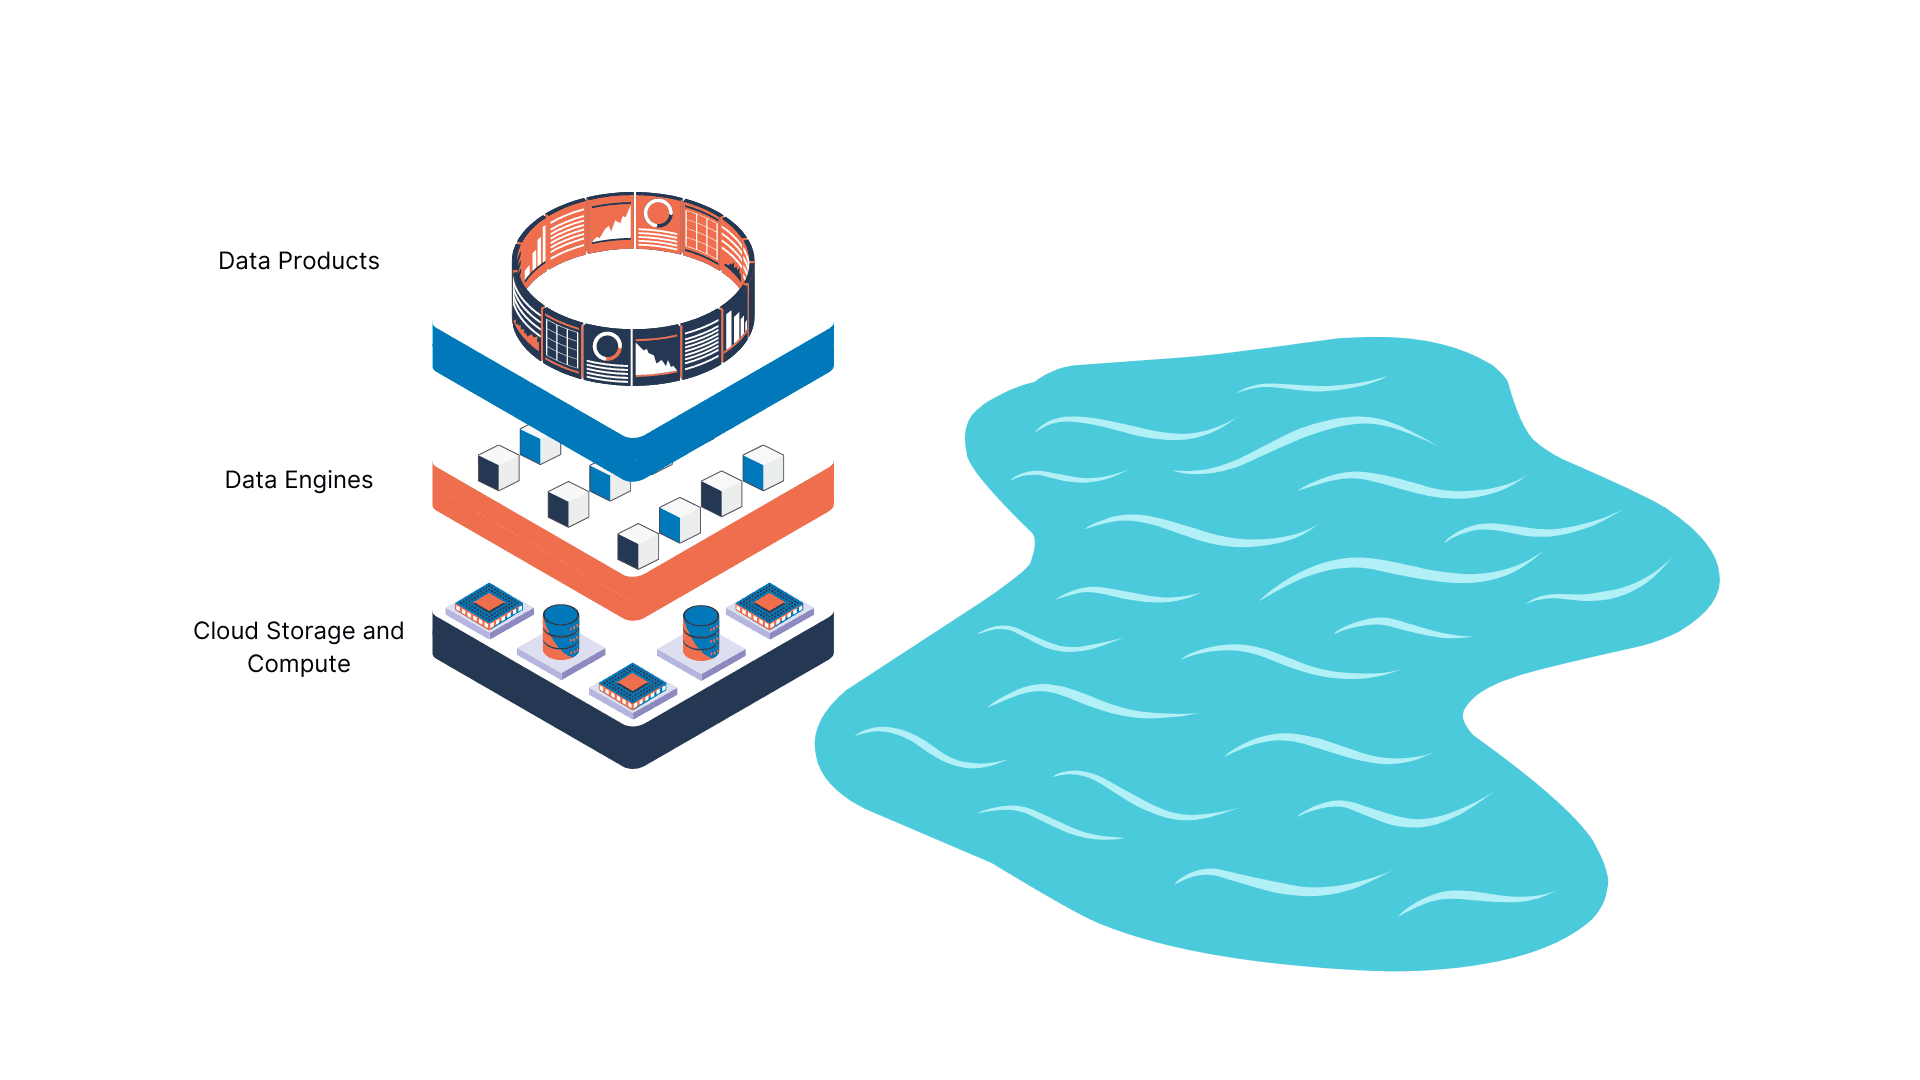
The term covers everything a company uses to work with data: the sources it comes from, the pipelines that move it, the platforms that store it, the transformations that shape it, and the reports, applications and models that use it.
Most data estates can be described in five stages:
Ingestion. Data arrives from applications, databases, files, event streams and third-party tools, through managed connectors or custom jobs.
Storage. Data lands in a warehouse, a lakehouse or object storage, such as Snowflake, BigQuery, Databricks or Amazon S3.
Processing. Pipelines clean, join and model the data, usually with tools such as dbt, Airflow or Dagster.
Analysis. Analysts and data scientists query the modeled data, and applications and machine learning models read from it.
Visualization. Dashboards and reports in tools such as Looker, Tableau and Power BI present the results to the rest of the business.

Each stage has its own tools and owners, and usually its own bill. The estate is all five, plus the connections between them. A table in the warehouse matters because of the dashboard it feeds, and a dashboard is only as current as the pipeline behind it.
How a data estate falls out of order
Few companies design their data estate. It accumulates. A team adds a connector to answer one question. Someone builds a pipeline for a launch, then a second one because the first is hard to change. A dashboard gets made for a quarterly review and is never opened again once that quarter closes. Each addition made sense on the day it was made.
Over the years, three things tend to happen. Data that once had a purpose keeps being refreshed after the people who used it have moved on. New tools are added for the problems of the moment, and older ones stay in place because nobody is sure what still depends on them. The datasets the business relies on most end up on the same schedules, monitoring and budget as everything else, because nothing in the stack tells them apart. We think this last problem does more damage than the clutter.

The data team rarely grows as fast. Fewer people end up looking after more pipelines, and the time to ask what each one is for is the first thing to go.
Signs an estate is out of order
Warehouse and tool costs rise faster than the number of people using the data.
Nobody can say with confidence which tables could be deleted without breaking something.
The same metric shows different numbers in different dashboards.
Alerts fire every day, and most of them are ignored.
An important report arrives late because its pipeline waited behind less important jobs.
New team members take weeks to learn where data lives and which sources to trust.
Questions about where a number came from take days to answer.
One or two of these is normal. Several at once usually mean the estate has grown without anyone keeping track of what it holds and why.
How to get a data estate in order
We’d do the work in this order, and we’d hold off on changing anything until the first three steps are done. Retiring a pipeline before checking who reads it is the quickest way to lose the business’s trust in the cleanup.

Take an inventory. List the sources, pipelines, tables, models and dashboards across all five stages, with an owner for each. A spreadsheet is enough to start.
Find out who uses what. Warehouse query history, BI view logs and access lists show which tables and dashboards are read, and by whom. Most platforms already record this. It is rarely collected in one place.
Work out what matters most. Rank datasets by how much the business depends on them: who reads them, what they feed, and who would notice if they stopped updating. A table the finance team reads at month end ranks above one a test job reads every hour.
Retire what nobody uses. For data with no readers, the options run from refreshing less often, to archiving, to removing the pipeline. Agree on limits with the owners first, and watch for readers nobody knew about for a few weeks afterward.
Match spend and effort to importance. Refresh important data as often as it is needed, and the rest less often. Give the pipelines behind important work a higher place in the queue, closer monitoring and tests.
Keep it in order. Assign an owner when a new pipeline is created, review the inventory on a schedule, and check usage again every quarter.
What an estate in order looks like
In an estate that is in order, the data team can answer four questions quickly: what data exists, where it comes from, who uses it, and how much the business depends on it. Costs follow use, so data nobody reads stops consuming compute. The datasets behind important decisions refresh on time and are tested. When one of them breaks, the people who rely on it hear first.
This matters more as companies run AI on their data. A model or assistant answers from whatever data it is given. If that data includes stale tables and two versions of the same metric, the answers carry both problems with them. Ask an assistant for last quarter’s revenue and it will answer from whichever revenue table it finds first. In an estate that is in order, there is only one.
Where to go next
The next guide in this series, A data estate audit for teams that grew faster than their data team, walks through the first three steps in detail. It comes with a data estate inventory template for recording what the audit finds.
We built Dataring to organize the whole data estate and act on it, so the estate stays in order after the first cleanup. If your team is in the middle of this work, or about to start it, we’d be glad to talk it through. Bring what you know about your estate so far, and we’ll look at where the cost and the risk sit. Book a call with us.